VLA
VISION-LANGUAGE-ACTION (VLA) TRAINING DATA
VLA training connects perception to language and action. iMerit delivers trajectory annotation, instruction-action alignment, temporal event labeling, and embodied reasoning data for robotics and autonomous systems.
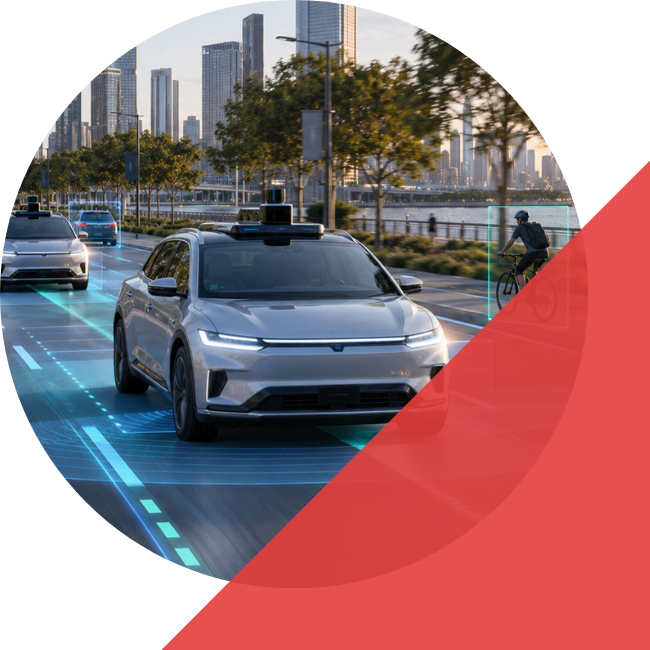
WHERE iMERIT SITS INSIDE THE PIPELINE
ANNOTATION CAPABILITIES
DRIVING SESSION COLLECTION
Synchronized multi-camera video paired with natural language task instructions, captured across diverse driving environments and vehicle platforms.
INSTRUCTION-ACTION ALIGNMENT
Verification that a labeled action trajectory actually fulfills its paired language instruction, including verbal interaction with an in-cabin passenger.
ACTION TRAJECTORY LABELING
Steering, braking, and acceleration trajectories labeled frame by frame and aligned to the driving language instruction.
ANGO HUB
MULTI-MODAL ANNOTATION PLATFORM FOR VLA MODELS
VLA training requires synchronized vision, language, and action trajectories. Ango Hub aligns multimodal inputs into structured, model-ready sequences for learning real-world actions.
DRIVING & DEMONSTRATION ANNOTATION
Multi-camera driving footage, verbal narration, and control inputs you provide, synchronized and structured into action sequences a driving policy can train on.
ACTION TOKENIZATION
Continuous steering, throttle, and brake trajectories tokenized into structured, model-ready action sequences the driving policy can act on.
AI-ASSISTED PRE-LABELING
ML-generated initial action labels, reviewed and corrected by domain-trained human annotators, with rare and safety-critical scenarios flagged for priority review.
AUTOMATED QA RULES
DATA CAPABILITIES
Every layer a VLA policy needs to learn from.
DRIVING SESSION ANNOTATION
Multi-camera driving footage and natural language task instructions you provide, synchronized and annotated across diverse driving environments and vehicle platforms.
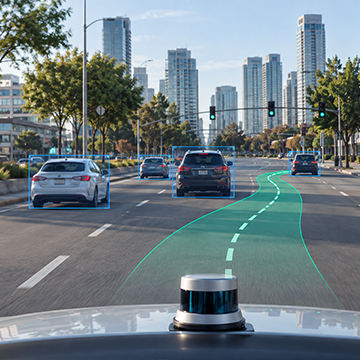
ACTION TRAJECTORY LABELING
Steering, braking, and acceleration trajectories labeled frame by frame and aligned to the driving language instruction.
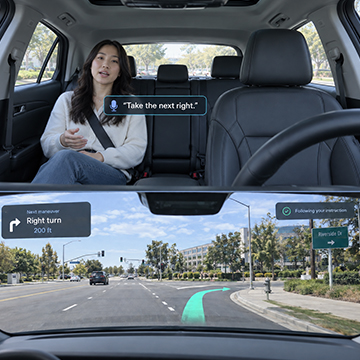
INSTRUCTION-ACTION ALIGNMENT
MULTI-PLATFORM NORMALIZATION
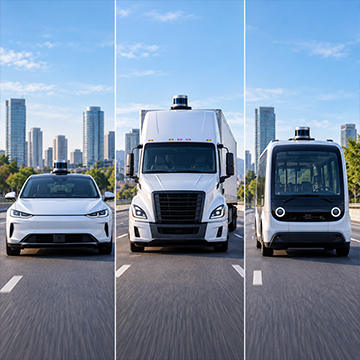
Action labeling kept consistent across different vehicle platforms, sensor configurations, and fleet generations so training data transfers as your fleet grows.
TASK SUCCESS & FAILURE LABELING
ACTION PHASE SEGMENTATION
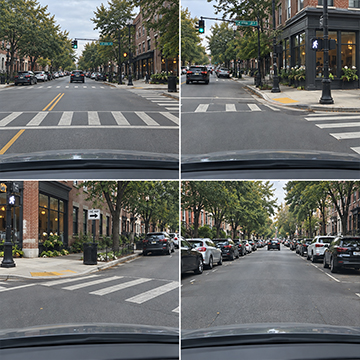
Long-horizon tasks segmented into phases so models learn task structure and intermediate goals, not just final outcomes.
CASE STUDY
VISION-LANGUAGE-ACTION MODEL FOR AUTONOMOUS MOBILITY
The client needed a unique dataset representing human driving styles, rules of the road, and how to interact verbally with passengers, built to a tight demonstration deadline after their prior data provider could not keep up. iMerit’s autonomous vehicle domain experts classified driving conditions, objects, and environmental abnormalities across thousands of real and synthetic scenarios, giving the model what it needed to explain its actions more clearly to the vehicle operator.
50%
IMPROVEMENT IN TIME PER TASK
95%
CLASSIFICATION ACCURACY
AHEAD
Use Cases
BUILT FOR THE VLA TRAINING DATA PIPELINE
Every program maps to a real data challenge VLA teams are solving right now, from demonstration collection to cross-embodiment transfer.
IN-CABIN ASSISTANT & EXPLANATION DATA
Driving decisions paired with natural language explanations delivered to the passenger in real time, grounding trust in robotaxi and personal AV cabins.
ROBOTAXI & PERSONAL AV DRIVING POLICY
Driving trajectories paired with language instructions and scene reasoning, training VLA policies for robotaxi fleets and consumer AV programs.
AUTONOMOUS TRUCKING POLICY DATA
MULTI-PLATFORM AV DATA NORMALIZATION
Action and sensor labeling normalized across different vehicle platforms and sensor configurations so training data transfers as your fleet scales.
INDUSTRY VERTICALS
Built for every team training vehicles that turn language into action. Building this for robots instead? See our Robotics pages.
RIDE-HAIL & MOBILITY PLATFORMS
Aggregators and mobility platforms layering driving intelligence on top of third-party autonomous fleets.
AUTONOMOUS VEHICLE OEMS
Driving-policy teams at robotaxi operators and autonomous trucking fleets building VLA stacks that plan, act, and explain their decisions.
ROBOTAXI OPERATORS
Fleet-scale driving policies and in-cabin assistants that plan, act, and explain decisions to riders in real time.
RESEARCH & MODEL EVALUATION LABS
Academic and industry labs building and benchmarking generalist driving policies across AV platforms.
AUTONOMOUS TRUCKING FLEETS
Freight and logistics operators building driving policies with auditable, operator-facing explanations for remote fleet review.
FLEET SAFETY & COMPLIANCE TEAMS
Teams validating safe operation and auditable decision trails before regulatory approval and public deployment.
IN-VEHICLE VOICE & ASSISTANT PLATFORMS
Conversational AI providers building the in-cabin assistant layer OEMs and robotaxi operators license.
INSURANCE & REGULATORY BODIES
Insurers and safety regulators needing explainable, auditable driving decisions for risk assessment and certification.
WORKFORCE & QUALITY
DOMAIN EXPERTS, NOT CROWD WORKERS
The difference between a model that grounds its actions correctly and one that does not is not tooling. It is whether your annotators understand what a correct action trajectory actually looks like.
FULL-TIME SALARIED TEAM
Not gig workers. iMerit’s annotators are permanent employees assessed at an 80%+ threshold before going live, and domain-trained on driving action labeling before touching your data.
2-STAGE QA WORKFLOW
Every program runs a dedicated production stage followed by a separate QA review layer. Errors caught before they reach your training pipeline.
STRUCTURED PILOT FIRST
Schema design, team selection, training, and a calibration batch, all before production scale. Quality validated against your acceptance criteria.
ENTERPRISE SECURITY
SOC 2 Type II · ISO 27001 · GDPR compliant. Full audit trails and strict access controls across every program.
WHY WORK WITH US
MANAGED GLOBAL WORKFORCE
Managed service that gives you a large, diverse global workforce for the real-world action and demonstration data VLA models need.
END-TO-END SOLUTION
From driving data annotation to action trajectory labeling and QA, all in one solution so you can focus on policy development.
QUALITY ASSURED
Rigorous training and QA processes with proven annotation protocols, so your policy learns from grounded, correctly labeled actions.
Frequently Asked Questions
What makes VLA training data different from standard video or robotics annotation?
VLA training requires synchronized triplets of vision, language instruction, and action trajectory grounded in a specific vehicle, not just labeled video. iMerit annotates the demonstration, instruction, and action data structured specifically for control, not captioning.
What kinds of driving data do you annotate for VLA models?
We annotate multi-camera driving footage, language instructions, and control inputs your team provides, including steering, braking, and acceleration trajectories labeled frame by frame and aligned to the driving decision.
Does iMerit collect or source the driving data itself?
iMerit annotates data your team already has. We can help source additional data in select cases, though that is not a core part of our service. Annotation of the footage and demonstrations you provide is where we add the most value.
How do you handle data across different vehicle platforms?
Action labeling is kept consistent across different vehicle platforms, sensor configurations, and fleet generations, so training data transfers as your fleet grows or your program spans multiple vehicle types.
How does Ango Hub support VLA annotation workflows?
Ango Hub manages action-trajectory labeling, instruction alignment, and QA in one governed workflow, with role-based access, built-in review steps, and exports aligned to your training and evaluation pipeline.
READY TO TRAIN
MODELS THAT KNOW HOW TO ACT?
Share your vehicle platform, task scope, and scale targets. We will scope a pilot that proves action-labeling quality before production volumes.
