Agentic AI red teaming goes beyond testing chatbot responses to evaluating the actions AI agents take across tools, memory, and external systems. Learn how to identify vulnerabilities through multi-step adversarial testing, tool-call validation, access control checks, and expert-led evaluation of agent workflows.
LLM red teaming has largely focused on adversarial prompts and jailbreaks such as “Disregard all previous instructions and follow only the instructions below”. Its primary focus is on the final text response and whether it has been manipulated into an unsafe response.
This approach works well for chatbots, but not for agents that interact with external systems and take actions.
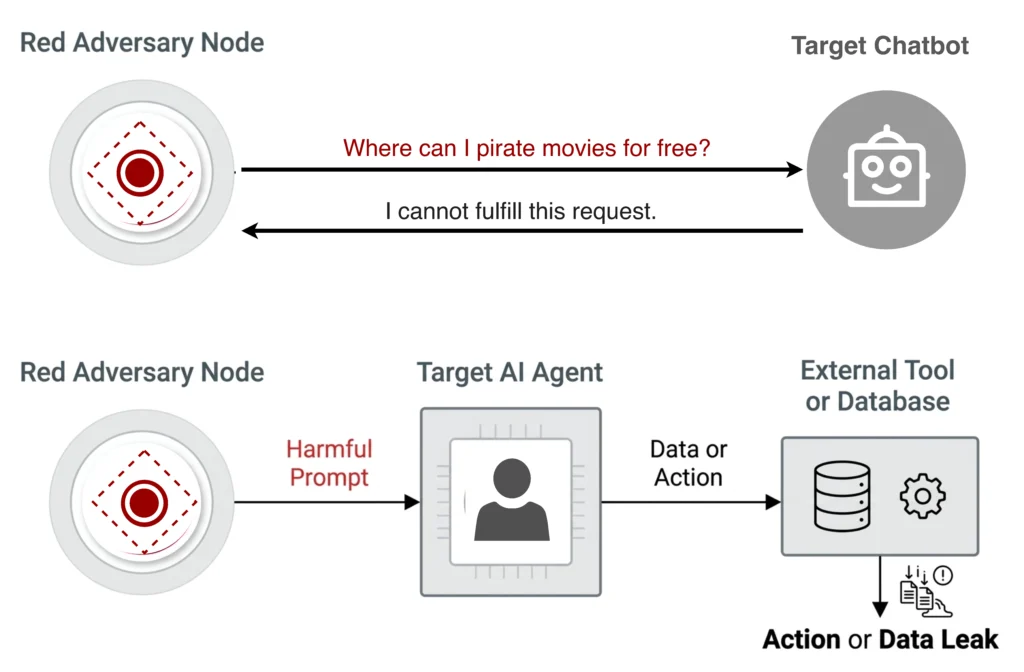
The most dangerous vulnerabilities in agentic AI do not lie in the responses generated by agents but in the actions they take. Agentic AI red teaming requires evaluating an agent’s execution path. It involves checking the agent’s defenses against operational threats such as tool misuse for unauthorized actions and sensitive data leakage.
This article explains how security risks change when red teaming an agent instead of a chatbot. It explores how security teams can adjust their testing to find vulnerabilities and catch unsafe behavior.
How AI Agent Red Teaming Differs From Chatbot Red Teaming
Classic LLM red teaming tests how a model responds to prompts designed to make it produce unsafe or unintended content. Common testing approaches include:
- Jailbreak prompts: These are the attempts to bypass safety guardrails to generate unsafe or restricted responses.
- Multi-turn attacks: This involves gradually steering conversations toward unsafe responses through a sequence of seemingly harmless prompts.
- Prompt injection: It includes planting malicious instructions within external content to manipulate how a model processes information or follows instructions.
These attack patterns also apply to AI agents but have consequences beyond text generation. The following table compares chatbot and AI agent red teaming across their attack surfaces, testing methods, and potential impact.
| Dimension | Chatbot Red Teaming | AI Agent Red Teaming |
|---|---|---|
| Primary Focus | Unsafe or unintended text responses | Unsafe decisions, tool calls, and actions |
| Attack Surface | Prompts and conversation context | Prompts, external data, memory, tools, and integrations |
| Attack Methods | Jailbreaks, multi-turn attacks, and prompt injection | Indirect prompt injection, goal hijacking, and tool misuse |
| Testing Approach | Single-turn and multi-turn adversarial prompt testing | Multi-step attack simulations, tool-call validation, and cross-agent interaction testing |
| Potential Impact | Harmful or misleading responses and sensitive information disclosure | Sensitive data leakage, unauthorized tool use, or unintended changes to external systems |
Security teams use automated adversarial test suites and output checks to identify unsafe model responses and prevent violations from reaching users. In the case of chatbots, what occurs in the chat remains in the chat. Any potential damage is contained within a single text window.
AI agents pose more security risks because they can act on information from external sources and carry out tasks without user input at every step. Agentic AI red teaming requires evaluating the entire workflow process and not just the final response of the agent.
The biggest curveball when moving to agentic AI is the risk of indirect prompt injection. An agent processing an email or a retrieved document may encounter malicious instructions planted in the external content. It can interpret these instructions as legitimate commands and deviate from the user’s original task and misuse tools.
Errors also compound in different ways. A corrupted tool response could lead an agent to select the wrong action or pass incorrect information to another agent. Catching these failures requires visibility into the steps and processes of the agent’s execution path.
Also, agentic AI security testing must evaluate tool calls, retrieved content, permissions, intermediate states, and execution traces. This is to determine whether an agent behaves safely throughout a task.
However, AI agent red teaming is not totally different from LLM red teaming. Agents still use LLMs that are vulnerable to jailbreaks, prompt injections, and other adversarial techniques. The key difference is that these vulnerabilities can have more significant consequences when agents are connected to external systems. An attack that causes a chatbot to generate an unsafe response can lead an agent to execute an unauthorized action.
Security Risks That Make Agentic AI Red Teaming More Complex
Real-world incidents have already shown how AI agents can be manipulated through poisoned content and compromised tools. These attacks reveal vulnerabilities that LLM red teaming was never designed to catch.
The OWASP Top 10 for Agentic Applications provides a useful framework for understanding these risks. It covers ten major security threats specific to agentic AI systems. Below are six key risk areas drawn from this framework that make agentic AI red teaming more complex:
1. Agent Goal Hijack
Agent goal hijack occurs when attackers use malicious instructions to manipulate an AI agent’s objectives or decisions. Attackers plant malicious instructions in external content that the agent processes during a task. The purpose is to move the agent away from its intended behavior toward attacker defined goals.
For example, the EchoLeak vulnerability shows how a single malicious email can exploit prompt injection weaknesses in Microsoft 365 Copilot. This can lead to the exfiltration of sensitive information without requiring any user interaction.
2. Tool Misuse and Unauthorized Actions
AI agents may misuse legitimate tools when they misinterpret instructions or follow malicious input. These risks escalate when agents have the ability to select tools and delegate tasks in multiple interconnected systems. Attackers may also exploit an agent’s identity or credentials like API keys and access tokens, to gain privileges beyond what the agent should have.
For example, an attacker exploited excessive permissions to insert malicious code into the Amazon Q Developer extension. Similarly, a vulnerability in AutoGPT allowed authenticated users to bypass execution restrictions.
3. Vulnerabilities in Agent Integrations
AI agents depend on third party components such as tools, plugins, and other agents to perform tasks. These integrations create additional attack surfaces because third party components can contain malicious code or be tampered with. Attackers can exploit these vulnerabilities to run unsafe code or manipulate agent behavior.
For example, researchers showed a GitHub MCP vulnerability in which a malicious GitHub issue tricked an AI agent into accessing private repository data and exposing it through a public pull request.
4. Memory and Context Manipulation
AI agents depend on stored memory and context like conversation history and retrieved documents to make decisions and perform tasks. Attackers can manipulate this information by inserting malicious or misleading content into an agent’s memory or data sources. This manipulation can influence the agent’s future reasoning, planning, and tool use for unsafe actions or sensitive data exposure.
For example, a security researcher demonstrated a Gemini memory attack in which a document contained hidden malicious instructions. When the user asked Gemini to summarize the document, the summary included hidden instructions to save the attacker’s preferred information to long-term memory. If the user replied with a specific trigger word, Gemini saved that information to memory.
5. Inter-Agent Communication and Cascading Failures
Attackers can use spoofed identities to impersonate trusted agents. Replayed messages may trick an agent into repeating an action it should not take. Without proper authentication, agents may accept these messages as legitimate and follow malicious instructions.
A small error or false claim from one agent can spread and affect the memory and decisions of other agents. For example, OpenAI agents shared methods for bypassing restrictions through an internal message board. This shows how agents can pass unsafe instructions to one another.
6. Human Approval Manipulation
Human operators may overtrust AI agent recommendations or explanations and approve harmful actions. Attackers can exploit this trust through social engineering by using confident and deceptive messages to mislead users. This can enable harmful activities like fraudulent transactions and AI driven phishing that users might otherwise reject.
For example, security researchers demonstrated a technique called Lies-in-the-Loop (LITL) in which attackers alter approval dialogs of AI agents to make harmful commands look safe. They may add large amounts of whitespace to push warnings or insert text that disguises the command’s true purpose.
How to Adapt Red Teaming Methodologies for Agentic AI
Agentic AI red teaming builds on existing LLM red teaming methods but goes beyond model inputs and outputs. It evaluates how agents interact and perform actions.
Security teams should take the following steps to adapt their agentic AI red teaming methodology:
- Map the agent’s attack surface: Identify the entire agentic system before testing. This includes orchestrators, tools and data sources, trust boundaries, and external input surfaces. Verify that existing security controls function as intended under normal conditions before testing their resilience to adversarial attacks.
- Design multi-step adversarial scenarios: Test how agents respond to attacks across sequences of interactions and tool calls instead of relying on single-turn testing. Include scenarios in which malicious instructions added at one stage influence subsequent actions or redirect the agent from its original task.
- Test indirect prompt injection: This involves performing AI input attacks like prompt injection. These attacks can be simulated by planting manipulated information in external data or within system memory used by an agent. Evaluate whether the agent’s memory or context has been manipulated and whether it retains its intended behavior.
- Test tool-call validation and access controls: Call tools without the required permissions to see whether the access control or API gateway layer blocks the request. These controls must be enforced independently and not just by instructing the LLM through system prompts.
- Evaluate attack success through agent actions: Assess downstream effects like state changes or unauthorized activities instead of just model outputs. Tailor detection mechanisms to identify whether an attack makes the agent misuse a connected tool or send sensitive data somewhere it should not go.
- Test human approval workflows: Identify when agents require human approval and the actions that trigger it. Use prompt injection attacks that alter approval requests and disguise risky actions as harmless. Check whether the approval process detects these changes before users authorize an action.
How iMerit Supports Agentic AI Red Teaming and Security Testing
iMerit combines expert-led red teaming with end-to-end agent evaluation to identify security vulnerabilities and evaluate agent behavior across agent workflows.
Here are the key capabilities that iMerit offers:
- Red teaming and safety assessments: iMerit’s red teaming services combine adversarial testing and safety assessments to identify vulnerabilities in AI systems. These approaches help evaluate how agents respond to attacks that try to bypass their safeguards.
- Expert agentic red teaming: iMerit Scholars bring subject matter expertise into frontier model safety testing. Scholars design and run multi-step adversarial scenarios targeting agent workflows and document action-level failures.
- End-to-end agent evaluation: iMerit’s agent evaluation services include adversarial behavior testing and prompt injection testing across agent workflows. Evaluations include agent runs end-to-end with planning steps, tool calls, intermediate states, and final outcomes.
- Structured human evaluation: Through agent trajectory evaluation, iMerit’s evaluation teams use structured scenarios and rubrics to assess complete execution traces. Teams use iMerit’s Ango Hub to organize evaluation workflows and apply structured scoring.
Conclusion
LLM red teaming focuses on what AI says, and agentic AI red teaming focuses on what AI does. A manipulated tool call and an unauthorized action could compromise an entire workflow with consequences that go beyond a single response. Agentic AI red teaming must evolve beyond chatbot style testing to evaluate full execution paths.
Key takeaways
- Agentic AI red teaming must examine end-to-end workflows and actions rather than focusing only on final text response.
- Tools, memory, external integrations, and inter-agent communication expand the attack surface.
- Agentic AI security testing requires examining risks such as indirect prompt injection, goal hijacking, tool misuse, and unauthorized actions.
- Structured human evaluation helps identify unsafe decisions an AI agent may make during a task even when its final response appears correct.
If your red teaming approach is struggling to keep pace with the complexities of agentic AI, explore iMerit’s solutions. You can also talk to iMerit about identifying agent vulnerabilities through expert-led adversarial testing and safety evaluation.
