You can trust synthetic data once it earns that trust. Validated against real distributions and reviewed by experts, synthetic datasets improve coverage and lift the precision of model outputs. Left unchecked, they teach models the wrong lessons and degrade performance. The safe default is to treat every synthetic sample as a claim to be tested before training begins. Synthetic data now feeds a growing share of generative AI development, and that shift raises the stakes for getting validation right.
Why Teams Reach for Synthetic Data
Real data is expensive to collect, slow to label, and constrained by privacy rules. Synthetic data gives developers a way to fill gaps, cover rare events, and protect sensitive records without waiting on the field.
Sources of Synthetic Data, From Simulation to Generative Models
Synthetic data comes from two broad sources. Simulators and game engines render scenes with known ground truth, while generative models such as Generative Adversarial Networks (GANs) and diffusion models learn patterns from real samples and produce new ones.
The Upside in Coverage, Rare Cases, Cost, and Privacy
Well-built synthetic data expands coverage of situations that real datasets miss, including hazardous or infrequent events that are costly to record. It also lowers collection expenses and limits exposure of personal information.
The Quality You Cannot Take on Faith
Those benefits hold only when the data reflects reality. Gartner warns that by 2027, most data and analytics leaders will face serious problems managing synthetic data, with real risk to model accuracy and compliance.
Why Multimodal Synthetic Data Is Hard to Trust
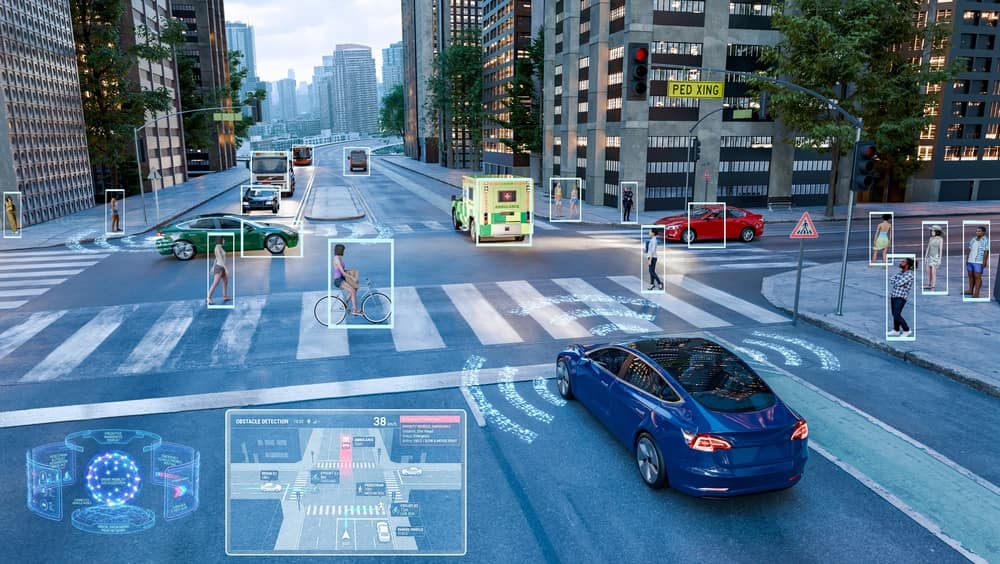
Multimodal datasets combine images, video, LiDAR, radar, and text. Each modality can carry its own flaws, and the combination multiplies the ways a dataset can drift from reality. A domain gap separates synthetic data from real data in each modality, from the appearance of a rendered image to the geometry of a point cloud, and it needs measuring before the data earns trust for training.
Artifacts and Unrealistic Patterns in Image, Video, and Sensor Data
Rendered images can show repeated textures, unnatural lighting, or physics that no real camera would capture. Synthetic video can move too smoothly or light a scene without the flicker of real footage. Synthetic sensor data, such as LiDAR point clouds, may lack the noise and occlusion patterns that appear in the field.
Keeping Modalities Aligned and Physically Plausible
A synthetic scene has to stay consistent across modalities, since sensor fusion depends on the streams agreeing. A pedestrian in the camera frame should appear in the LiDAR return at the same position, moving in a way that respects real physics.
Hidden Distribution Gaps Between Synthetic and Real
Even realistic samples can cluster in a narrow slice of the real distribution. These gaps resist visual inspection and show up only when a model meets genuine data.
How Weak Synthetic Data Hurts Model Performance
Poorly validated synthetic data does not fail loudly. It shifts what a model learns in ways that surface after deployment.
Models That Learn Artifacts Instead of Real Signal
A model can latch onto rendering artifacts that happen to correlate with labels in the synthetic set. On real inputs those shortcuts vanish, and accuracy drops.
The Sim-to-Real Gap
The distance between simulated and real conditions leaves models confident in the lab and fragile in the field. Closing that distance takes deliberate testing on real benchmarks.
Overconfidence and Blind Spots at Inference
When training data misses parts of the real distribution, models grow overconfident on inputs they never truly saw. Adversarial red teaming exposes these blind spots before they reach production.
How to Validate Synthetic Data Before You Train On It
Validation turns synthetic data from a liability into an asset. A layered set of checks catches different failure modes.
Statistical Checks Against Real Distributions
Compare feature distributions, class balance, and correlations between synthetic and real samples. Divergence metrics such as Kullback-Leibler divergence and Maximum Mean Discrepancy flag where the synthetic set drifts, and Fréchet Inception Distance does the same for image data.
Human and Expert Review of Realism and Edge Cases
Domain experts spot problems that statistics miss, from implausible scenes to mislabeled edge cases. A metric can confirm the pixel distribution looks right while missing a shadow that falls the wrong way or a road sign that no country uses. Experts also judge whether rare cases behave as they would in the field, which grounds the data in real-world behavior.
Downstream Testing on Real-World Benchmarks
The strongest test is model performance on held-out real data. Train with the synthetic set, then measure accuracy against established real-world benchmarks, such as nuScenes or the Waymo Open Dataset for autonomous mobility. Holding out a slice of proprietary real data gives an internal benchmark that matches the exact deployment conditions.
Blending Synthetic and Real Data Carefully
Mixing synthetic and real samples usually beats either source alone. Real data anchors the model in true conditions, while synthetic data fills gaps and adds rare cases that the real set lacks. The right ratio depends on the task, so sweep a few blends and compare each against a real benchmark before settling on one.
Best Practices for Trustworthy Synthetic Data
A few habits keep synthetic data honest across a project.
Treat Synthetic Data as Something to Verify
Assume every batch could carry hidden flaws until checks prove otherwise. A generator that worked last quarter can drift as its inputs or settings change, so trust earned once does not carry forward.
Validate Before It Enters the Pipeline
Gate synthetic data at the entry point so problems never reach expensive training runs. Catching a flawed batch early costs a review cycle, while catching it after training costs a full retrain.
Monitor Performance After It Joins the Mix
Track real-world metrics after synthetic data enters the set, and roll back quickly when quality slips. A steady drop on real benchmarks is an early sign that the synthetic portion has begun to degrade the model.
How iMerit Helps Teams Validate Synthetic Data
Synthetic data earns trust when experts stand behind it. iMerit delivers software-driven services for data annotation and model fine-tuning that unite automation, human domain experts, and analytics in one workflow. Our GenAI data work brings that same discipline to synthetic datasets, so what reaches your model has already been checked.
Our specialists review synthetic samples for realism, verify alignment across modalities, and surface the edge cases that break models in the field. Through our data annotation services, we validate distributions, label ground truth, and benchmark model behavior against real data before it ships.
To pressure-test a synthetic dataset or design a validation workflow for your next model, contact our experts and move to training with confidence.
References:
https://arxiv.org/abs/1406.2661
www.nature.com/articles/s41598-025-15480-0