A computer vision dataset is ready to train when its labels are accurate and consistent with an agreed taxonomy, its classes cover the conditions the model will meet in production, and its train, validation, and test splits are free of duplicates and leakage. A fully labeled dataset can still fail all three tests. When it does, the damage surfaces as stalled accuracy and misleading evaluations that send teams rebuilding the model instead of fixing the data. A short readiness review answers these questions up front and protects every computer vision training run that follows.
What Does a Training-Ready Dataset Actually Mean?
A training-ready dataset is one you can hand to a model with confidence that what it learns will transfer to real inputs. It carries correct labels, sensible class coverage, and clean separation between the data used to train and the data used to measure.
Ready to Train Versus Simply Labeled
A labeled dataset has annotations on every image. A training-ready dataset has annotations that are correct, consistent across annotators, and aligned to the schema your model expects. Those are different bars. A dataset can be fully labeled and still teach a model the wrong lessons if two annotators drew boundaries differently or applied class names loosely.
The Cost of Training on a Dataset Too Earl
Training too early wastes compute and sends you chasing problems that live in the data, not the model. When accuracy stalls, teams reach for new architectures, more layers, or longer schedules, while the real cause is a mislabeled class or a split that leaked. Catching these issues up front is cheaper than diagnosing them after a week of runs and a confusing evaluation.
What to Check Before You Commit to Training
Run four checks before training: coverage, class balance, label consistency, and leakage.
Coverage Across Real-World Conditions
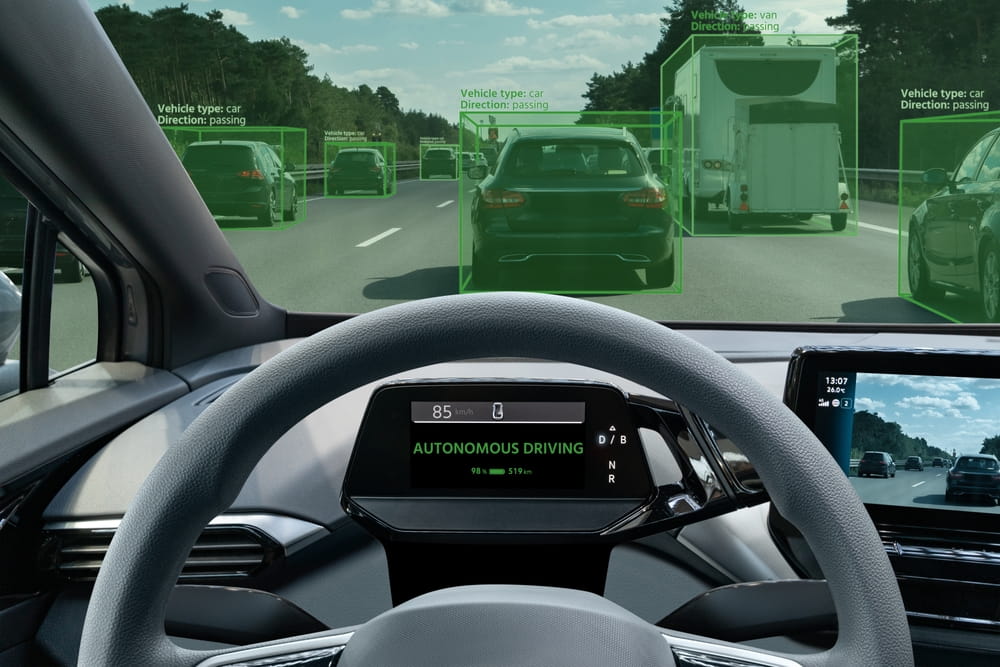
Check that your data spans the lighting, weather, camera angles, distances, and scene types your model will face in deployment. A pedestrian detector trained only on clear daytime footage will struggle at dusk or in the rain. Map the conditions of your target environment, then confirm the dataset has meaningful examples of each. Gaps here show up later as silent failures on inputs the model never saw.
Class Balance and Rare-Case Representation
Confirm that every class has enough examples to learn from, and pay special attention to rare but important cases. Severe imbalance pushes a model toward the majority class and leaves it weak on the categories that may matter most, such as a hazard that appears in a small fraction of frames. You do not need perfect balance, but you do need a plan for underrepresented classes through targeted collection, augmentation, or weighting.
Label Consistency and Taxonomy Alignment
Verify that annotators applied the same rules the same way and that every label maps to your taxonomy. Inconsistent labels are a common and underrated problem. Researchers who audited ten widely used benchmarks found an average of at least 3.3 percent label errors, with roughly 6 percent in the ImageNet validation set, enough to change which model looks best. Clear guidelines, spot checks, and inter-annotator agreement (IAA) keep this in line.
Duplicate and Leakage Checks Across Splits
Make sure no image, or near-duplicate, appears in more than one split. Data leakage between training and test data produces scores that look strong in evaluation and collapse in production, and it has driven documented reproducibility failures across scientific fields. Deduplicate first, then split, and watch for subtler leaks such as frames from the same video clip landing on both sides.
Where Metrics Stop and Judgment Begins
Metrics confirm consistency, but a person decides readiness.
What Quality Scores Can and Cannot Tell You
Quality scores tell you how consistent your labels are, not whether they are right for your use case. Inter-annotator agreement, label counts, and automated checks flag obvious trouble, yet they can all look healthy on a dataset that still misses the scenarios your model needs. Read scores as evidence, not a final verdict.
Why Edge-Case Readiness Needs a Human Call
Deciding if your rare and ambiguous cases are handled well enough takes a person who knows the domain. Edge cases are where models fail in the field, and a reviewer with context can tell a dataset that merely contains hard examples apart from one that labels them correctly. Domain experts bring that read to projects with nuanced taxonomies.
A Practical Readiness Checklist for Vision Teams
A readiness checklist comes down to two calls: signing off or sending the data back for more work.
Sign-Off Criteria Before Training
Sign off once coverage matches your deployment conditions, classes are balanced or accounted for, label consistency clears your agreed threshold, and splits are clean of duplicates and leakage. Make those thresholds explicit and shared across the team, so readiness holds up as a consistent standard instead of a judgment that shifts from one reviewer to the next.
When to Send Data Back for More Curation
Send data back when a check fails in a way that would bias learning, such as a missing condition, a class with too few examples, or labels that drift from the schema. Returning a dataset for more data annotation may seem like a delay, but it is the faster path overall because fixing the inputs takes less time than untangling a model trained on flawed inputs.
Get an Expert Read on Your Dataset’s Readiness With iMerit
Most readiness problems are easy to miss and expensive to ignore. iMerit has labeled, enriched, and segmented more than 100 million images and videos. Our vision annotation teams work through complex edge cases and nuanced taxonomies so your data earns its place in training. Expert-led annotation and quality control bring a trained eye to label consistency and coverage, so you learn what is ready and what needs another pass before training.
Talk to our experts and start your next run with confidence in the data behind it.
References:
https://arxiv.org/abs/2103.14749
